
Efficient Hybrid Post-Quantum File Security Framework
Журнал: International Journal of Computer Network and Information Security @ijcnis
Статья в выпуске: 5 vol.18, 2026 года.
Бесплатный доступ
The shift towards a quantum-secured future has driven the demand for more practical ways of protecting files that can add post-quantum cryptographic components without creating a massive increase in computational or storage demands. This study proposes and tests a hybrid file-security approach combining a post-quantum key encapsulation mechanism and authenticated symmetric encryption for real-world file security. An experimental research design was followed with the use of a valid subset of GovDocs1 corpus as the evaluation sample, and the files were stratified based on the format, size and entropy characteristics. Three different architectures were designed, built and evaluated for design evolution from direct lattice-style architecture to standards-based hybrid architecture. Correctness, runtime, and ciphertext expansion were used to measure performance and compared to other files of various types and data characteristics. The results demonstrate the capability of the final framework to retain the exact reconstruction of the file and gain significantly in storage efficiency and execution time over previous model generations. A comparison of performance over different heterogeneous categories of files showed no significant difference, and overhead was seen to be a consistent decreasing function of file size. The results show that a hybrid design that can provide quantum resistant key protection and efficient authenticated encryption can be used to provide practical post-quantum-ready file security. The study offers an empirically supported framework for the security of files in a post-quantum era and offers a repeatable foundation for research into implementing it for deployment.
Короткий адрес: https://sciup.org/15020703
IDS: 15020703 | DOI: 10.5815/ijcnis.2026.05.07
Текст научной статьи Efficient Hybrid Post-Quantum File Security Framework
The rapidly increasing potential of quantum computing technologies poses a fundamental challenge to the existing cryptographic systems, particularly those based on classical hardness assumptions such as the integer factorization and discrete logarithm problems. With the continuing development of quantum algorithms, security of widely used cryptographic protocols has turned into a critical issue in both academia and industry. Moving towards quantumresistant security protocols is thus not a dream but a necessity to protect digital infrastructure. This transition has been recognized formally via standardization activities, such as the ones being led by the National Institute of Standards and Technology (NIST) to identify and formalize Post-Quantum Cryptographic (PQC) algorithms for long-term deployment [1].
In parallel, other estimates of quantum capabilities timelines suggest that soon enough, adversaries might be able to exploit quantum vulnerabilities and decrypt data that is already encrypted today [2]. The motivating threat model for this situation is that of ‘harvest now, decrypt later’, and this is why it is important to implement solutions that are quantum-resistant before the arrival of quantum computers on a large scale. In this context, file security as a field of storage, transmission and archival protection of digital content becomes a critical application field that urgently needs to be addressed.
A long-standing approach to file-level encryption is to use symmetric cryptographic primitives that are secure against quantum adversaries for the right parameter values. Secure key exchange and key management mechanisms are usually based on classical public-key cryptography, however, which is susceptible to quantum attacks. To cope with performance limitations in resource-constrained systems, lightweight cryptographic methods have been investigated, which typically focus on performance rather than long-term security assurances, and are therefore susceptible to quantum threats [3]. Therefore, hybrid cryptographic systems that combine quantum-resistant key encapsulation mechanisms with efficient symmetric encryption have gained increasing attention as a practical transition strategy.
This work is open access and licensed under the Creative Commons CC BY 4.0 License.
Among symmetric encryption schemes, Advanced Encryption Standard in Galois/Counter Mode (AES-GCM) is a well-established scheme for authenticated encryption, which provides confidentiality and integrity, and has been shown to be efficient and secure [4]. Meanwhile, lattice-based PQC algorithms, especially module learning-with-errors, have shown to be very resilient to quantum attacks and have been chosen as front runners during the quantum standardization process [5]. The progress shows that the hybrid encryption method using PQC key encapsulation combined with AES-GCM could be a promising approach for post-quantum secure file encryption.
Although there have been advances, there are still some gaps in the current literature. Most studies are theoretical or are based on algorithmic performance analysis, lacking in realistic environments to evaluate systems. Systematic reviews suggest that PQC algorithms are still being actively researched, but their implementation into a real application is still in its infancy and is not yet widespread particularly in the case of large scale or heterogeneous data [6]. What is more, the process of migrating to PQC adoption is complicated; it not only requires selecting an algorithm to be adapted but also performance, compatibility, and deployability aspects must be taken into account [7]. The implementation level concerns and design flaws that might permit side-channel attacks to occur even if the design itself is free from such attacks are further complicating these challenges [8].
In addition, key encapsulation mechanisms such as Kyber have demonstrated good performance properties but are usually used individually or under restricted communication model [9]. One gap in the literature is the lack of comprehensive evaluations of the entire workflows of file-level encryption, which includes PQC-based key-protection methods. Furthermore, new results in cryptanalysis have shown that some of the proposed schemes are vulnerable and therefore, it is crucial to ensure that any practical implementation is based on a well-tested and standard algorithm [10].
Therefore, in this work, the main topic of discussion is the lack of a framework for practically validated, postquantum, efficient file security that guarantees a robust cryptographic security level. Current methods make use of direct application of PQC primitives and typically suffer from either over-optimized processing and memory requirements or from lack of a comprehensive evaluation of the models using real-world datasets. But the gap between theory and practice of PQC and how to use it in file security day-to-day is there.
This can be considered a research gap because there are no empirical studies to assess hybrid PQC-based file encryption frameworks in realistic scenarios, with heterogeneous data sets and extensive performance metrics. To overcome this, appropriate cryptographic architecture needs to be designed and then systemically tested with various content types, file sizes and content features.
This work centers on the design and evaluation of a hybrid framework of overall file security which comprises the post quantum key encapsulation mechanism to be used in conjunction with the standard symmetric key encapsulation mechanism. This analysis is not conducted via formal security proof but on the merits of the performance, such as expansion ratio, encryption/decryption time and accuracy of reconstruction. The chosen dataset is heterogeneous and realistic, but only a portion of a larger dataset, and may not cover all distribution of files that will be seen in practice. The restrictions are indicated to aid interpretation of the results in the correct context.
This work is important as it plays an important role in the transition from PQC theory to its deployment. The study offers practical proof of the viability of hybrid cryptographic designs for real-world applications by presenting an efficient and scalable method for file encryption featuring post-quantum key protection. The approach is also methodologically valuable in that it combines several key steps in the construction of the stratified dataset, multidimensional performance analysis and staged model comparison into one evaluation pipeline.
The research is guided by the following objectives:
• To design a hybrid file security framework that integrates post-quantum key encapsulation with authenticated symmetric encryption.
• To evaluate the performance of the proposed framework across heterogeneous files using metrics of efficiency, storage overhead, and correctness.
• To compare successive architectural models in order to identify an optimal balance between security, scalability, and computational cost.
2. Literature Review3. Methodology
3.1. Research Design
The need for moving to post-quantum cryptographic systems has led to significant research and development in the area of various algorithmic families, with special focus on code-based and lattice-based constructions. The early work for designing a variant of McEliece confirms the possibility of achieving secure, but compact designs, which is one of the main weaknesses of classical code-based systems, namely large key size [11]. At the same time, optimizations of decoding mechanisms for such schemes are carried out, showing that performance bottlenecks can be reduced by algorithmic refinements as well as by implementing schemes in a hardware-aware manner [12]. These contributions demonstrate the feasibility of alternative post-quantum primitives but also show that these choices come with the cost of providing a simple solution versus a complex one, leading to a recurring trade-off between computational efficiency and structural complexity, making it difficult to directly integrate these into a general-purpose data protection system.
Many candidates have emerged in recent years as a result of the development of lattice-based cryptography, notably with schemes like CRYSTALS-Kyber. In hardware studies, Kyber is shown to be implementable with low latency and high throughput, suggesting its practical applications [13]. Additional studies of identity-based and enhanced encryption models reveal that post-quantum algorithms can be incorporated into existing cryptographic protocols and can be used in various applications beyond key exchange [14]. But, in many of these implementations, the environment is limited or is specifically tailored to a particular data scenario, meaning that the system may not be applicable to large-scale, heterogeneous data contexts, such as file systems.
One of the essential aspects of research in post-quantum cryptography is the security of its implementation, especially against side-channel attacks. Extensive leakage analysis of Kyber in industrial and embedded systems shows measurable leakage for realistic attack models [15]. Subsequent analysis finds there are specific implementation weaknesses pointing towards the need to carefully select parameters and integrate countermeasure implementation [16]. Even with the use of standardized candidates, such attacks as correlation power analysis still show that the candidates are susceptible to attacks if not hardened [17]. In the selected-ciphertext and side-channel attack areas, further research on the interactions that can be exploited confirms that the security of post-quantum systems is more complicated in practice than it appears in theory [18]. These results collectively emphasize that robustness of algorithms is not enough; the attack surface of actual deployments needs to be considered.
In parallel, the issue of optimizing performance by hardware acceleration has been investigated, especially for lattice-based operations like number theoretic transform. To demonstrate the high efficiency of the overall system, key computational parts of Kyber can be speeded up significantly by implementing the parts on a Field-Programmable Gate Array (FPGA), as shown in low latency FPGA implementations [19]. In networked environments, the same method is extended to include quantum resistant encryption in the pipelines used for communication between the Internet-of-Things applications, as described in [20]. Likewise, end-to-end quantum-resistant systems using a combination of Kyber-based key encapsulation and hardware-based entropy sources show the possibility of having reliable and high-performance quantum-resistant systems [21]. These studies are good informative work about efficiency and deployment methods, but they primarily deal with communication protocols or embedded systems, and do not deal with file-level encryption scenarios.
Although numerous works have been done, there is however a lack of research in practical application of the postquantum cryptographic mechanisms in file security mechanisms. In most previous research, the algorithms' performance metrics are examined, or the algorithms are tested under restricted settings, with little focus on the response of such systems to a mix of different file workloads. However, very few empirical studies have been conducted on the interaction between using post-quantum key encapsulation and authenticated encryption schemes on actual datasets, which includes a wide variety of file types and sizes as well as differing distributions of entropy. The lack of system-level validation introduces uncertainty about the scalability and efficiency of post-quantum solutions in the real-world data protection environment.
To fill this void, in the present study, a hybrid file security framework is proposed and tested combining key encapsulation based on the Kyber approach with authenticated encryption based on AES-GCM. The study is an empirical natural method analysis of a real-world dataset, which moves the analysis beyond algorithmic and hardware evaluations, to a more complete evaluation of file-level performance. Such placement is a change in the trend from only optimizing cryptographic functions, to the actual usage of post-quantum cryptography in file security applications.
This study used an experimental design with a quantitative approach to test the operational feasibility of file protection based on post-quantum methods under realistic conditions. The methodological logic was comparative and staged, examining three successive architectures: V1, a direct lattice-style prototype; V2, a custom hybrid prototype; and V3, the final standards-aligned framework integrating Kyber-768 key encapsulation with AES-GCM authenticated encryption. This design was chosen to study the impact of architectural refinement on correctness, storage overhead and run-time performance. The study thus considers a file security framework based on a practical PQC primitive and not proposing a new cryptographic primitive.
-
3.2. Dataset Preparation
-
3.3. Feature Characterization
-
3.4. Model Architecture
-
3.5. Encryption Workflow
-
3.6. Performance Metrics
-
3.7. Validation and Benchmarking
The real-world evaluation corpus is the GovDocs1 thread0 subset that is used in the empirical evaluation [22]. This corpus has been chosen due to its high external validity as it represents operational storage environments with heterogeneous file types, as opposed to being synthetic. The preparation pipeline was deterministic. In the beginning there were 991 files found. Following readability checks, integrity screening and excluding unsupported formats 515 were left as supported and usable records. Their composition was 257 PDF, 104 JPG, 84 TXT, 67 DOC, and 3 PNG files. This validated pool was then reduced to a subset of 134 which were used as a benchmark. To avoid skewing the results by any one type of bucket, and to provide a realistic size range and file content characteristic for files, stratification by file type and size bucket was employed. The final group of files contained 40 JPG files, 36 PDF, 31
TXT and 27 DOC. The PNG files were not part of the final benchmark as there were not enough to be able to make meaningful comparisons.
For each of the validated files, the file size (in bytes), the file extension, and the Shannon entropy were used to characterize it. The scalability and storage overhead were compared over payload magnitudes in terms of file size. The distribution of the bytes in the file was used directly to calculate the entropy as an empirical descriptor of the randomness of its content. The files were divided into four size buckets: 1KB-10KB, 10KB-100KB, 100KB-1MB, and 1MB-10MB. Fixed thresholds (low: < 5.0; medium: 5.0 to < 7.0; and high: ≥ 7.0) were used to define the different levels of entropy, implemented during the analysis pipeline. The thresholds were selected empirically to distinguish between files with a text-like distribution, mixed structure and highly compressed or image-like files in the observed distribution.
Three generations of the model were tested. V1 provided a proof-of-concept baseline of direct application to lattice-style file encryption with vectorized application of message embedding and adaptive noise. V2 used a hybrid approach that included a custom symmetric layer protecting the file payload, and a PQC-inspired approach protecting the session key. V3, the final framework, introduced two standardized primitives: Kyber-768 for key encapsulation, and AES-GCM for authenticated file encryption, replacing the custom components. In V3, the shared secret from Kyber encryption under the AES-GCM construction is directly used as the key for the AES-GCM, and the Key Encapsulation Mechanism (KEM) ciphertext is sent along with the nonce and the encrypted payload. All the models are programmed in Python 3.10, with the help of some packages such as NumPy, Pandas, Matplotlib, Cryptography and PyPQC.
For V3, each file was read in binary form and encrypted as a full AES-GCM payload. In the evaluation process, a KEM ciphertext and a shared secret were generated by encapsulating key 768 (the public key of the recipient) with it. Next, AES-GCM was used to encrypt the file, using the shared secret for the symmetric key and a random nonce of 96 bits. The transmitted cryptographic package therefore consisted of three components: AES-GCM ciphertext, nonce and Kyber KEM ciphertext. When the shared secret was recovered during decryption using the Kyber private key, it was then decapsulated and the payload decrypted using AES-GCM, which then checked for integrity. This is a description of the final implementation and should not be confused with a variety of the earlier prototypes using the chunk-based logic.
The following four metrics were used to evaluate it: expansion ratio, encryption time, decryption time and bytelevel correctness. For V3, the expansion ratio was defined as the total transmitted size of the AES-GCM ciphertext, nonce, and Kyber KEM ciphertext divided by the original file size. The time taken for encryption and decryption was measured using time.perf_counter() to provide high resolution measurement of execution latency. Correctness was evaluated by a byte level comparison between original and decrypted files, which is reported as mean byte accuracy and exact-match rate. These metrics were chosen as they represent efficiency, speed and reliability of storage.
There were 4 stages to the validation process. First, single-file tests verified exact recovery. Second, the model generations were tested on a small scale, so that they could be compared in controlled conditions. Third, in the iterative procedure of the model development, the variance and the behaviour of the confidence were investigated using repeated run statistical analysis for V2. Fourth, the final V3 was analysed for the whole subset of 134 files, as well as categorized for each file type, each file size bucket and per entropy level. In order to ensure the reproducibility, the random seed was set to 42 in all the sampling experiments, while the experiments were performed in the same software environment. The implementation used Python 3.10 on a Windows-based workstation with same runtime conditions across benchmark stages. No human subject or personal data were collected, and the study relied on the use of public files and so there was no formal consent procedure.
-
4. Results
-
4.1. Reconstruction Fidelity across the Full Evaluation Corpus
-
-
4.2. Cross-Model Efficiency in the Controlled Benchmark
The controlled small-batch benchmark has been used in cross-model comparison in order to measure the efficiency of the architectures under identical experimental conditions. The three models were differed markedly with regard to the storage overhead as well as runtime. V1 produced a mean expansion ratio of 32.02, whereas in V2, the mean expansion ratio was reduced to 1.11, and with further decrease to 1.09 in V3. The same was observed with the corresponding runtimes. Mean encryption time declined from 5.2995 s in V1 to 0.1176 s in V2 and 0.0015 s in V3. Mean decryption time declined from 2.6934 s in V1 to 0.0931 s in V2 and 0.000713 s in V3. The values show that at the end of the process, the standards-aligned design was correct and significantly cut down on the number of computations and growth of ciphertext. The ratio of the reduction of storage overheads is presented in Fig. 1.
The final V3 framework achieved perfect reconstruction across the complete 134-file benchmark. For every file in the evaluation subset, the decrypted output was byte-identical to the original input, yielding a byte accuracy of 1.0 and an exact-match rate of 1.0. This result was not limited to a single format or size class; was held across all evaluated DOC, JPG, PDF, and TXT files, as well as across all size buckets and entropy categories. The same correctness pattern was also observed in the controlled small-batch comparisons used for cross-model evaluation. No reconstruction failures, partial mismatches, or authentication errors were recorded during V3 execution.
To make the correctness comparison explicit, Table 1 reports the reconstruction metrics for the three model generations evaluated in the controlled benchmark.
Table 1. Reconstruction Accuracy across Model Generations.
|
Model |
Byte Accuracy |
Exact Match Rate |
|
V1_Direct |
1.000 |
1.000 |
|
V2_Hybrid_Custom |
1.000 |
1.000 |
|
V3_AESGCM_KEM |
1.000 |
1.000 |
Table 1 shows that V1, V2, and V3 all achieved perfect byte-level recovery in the controlled benchmark. The distinguishing differences between the models therefore arise from efficiency and overhead rather than correctness.
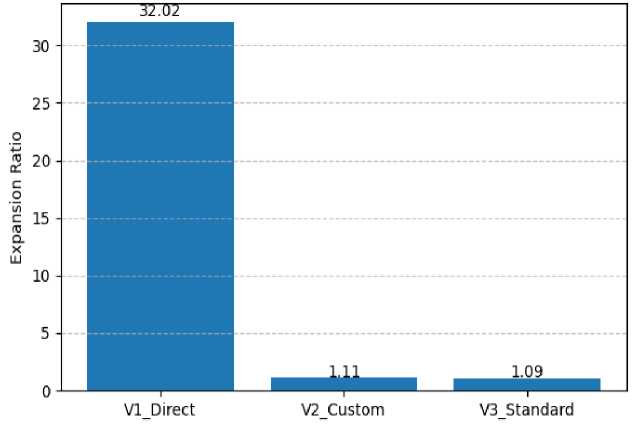
Fig. 1. Expansion Ratio Comparison for V1, V2, and V3.
Fig. 1 shows that V1 imposes very large ciphertext expansion, while both hybrid designs remain close to unity. The reduction from V2 to V3 is smaller in magnitude but still consistent. The runtime contrast between the hybrid designs is summarized in Table 2.
Table 2. Mean Runtime Comparison Between V2 and V3 in the Small-Batch Benchmark.
|
Model |
Mean Encryption Time (s) |
Mean Decryption Time (s) |
|
V2_Hybrid_Custom |
0.1176 |
0.0931 |
|
V3_AESGCM_KEM |
0.0015 |
0.000713 |
Table 2 shows that V3 reduced mean encryption and decryption time by approximately two orders of magnitude relative to V2 while maintaining the same correctness level.
-
4.3. Ciphertext Expansion Characteristics of the Final Framework
The final V3 model was then evaluated on the full 134-file corpus to characterize its storage behavior under realistic file heterogeneity. The overall mean expansion ratio was 1.0742, indicating that ciphertext growth remained limited for the final architecture. Expansion varied by file type, size, and entropy, but the variation was bounded and systematic rather than irregular. DOC files exhibited the lowest mean expansion ratio at 1.009, followed by PDF files at 1.049 and JPG files at 1.074. TXT files exhibited the highest mean value at approximately 1.160. This file-type variation is shown in Fig. 2.
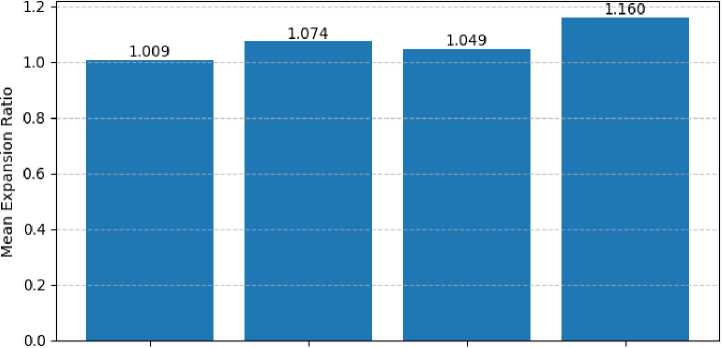
.doc .jpg .pdf .txt
File Type
Fig. 2. V3 Mean Expansion Ratio by File Type.
Fig. 2 shows that expansion remained close to 1.0 for all file types, with TXT files exhibiting the highest mean overhead. The separation between DOC, PDF, and JPG remained comparatively small. The effect of file size on expansion was stronger than the effect of format. Files in the 1MB–10MB range exhibited a mean expansion ratio of 1.000, and files in the 100KB–1MB range exhibited 1.003. By contrast, the 10KB–100KB bucket exhibited 1.022, and the 1KB–10KB bucket exhibited 1.343. The largest relative overhead therefore occurred in the smallest files, where fixed cryptographic metadata constituted a larger fraction of the final package size. Fig. 3 presents this size-dependent pattern.
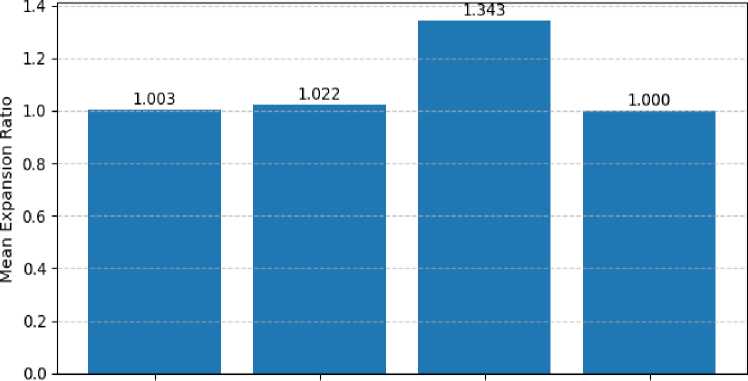
100KB-1MB 1OKB-1OOKB 1KB-10KB 1MB-10MB
Size Bucket
Fig. 3. V3 Mean Expansion Ratio by File Size Bucket.
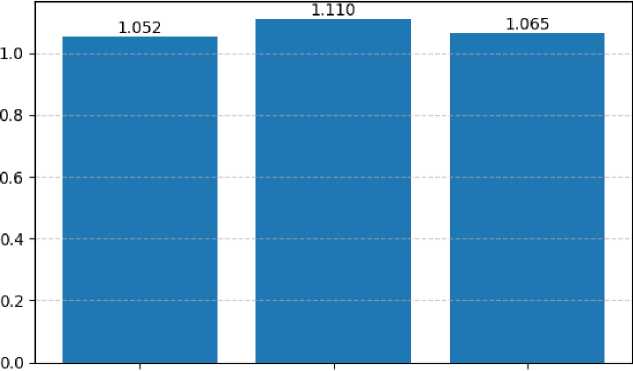
Fig. 3 shows that expansion approaches 1.0 as file size increases. The smallest files display the highest proportional overhead, whereas medium and large files remain near storage neutral. Entropy-based aggregation produced a comparable but weaker gradient. High-entropy files showed a mean expansion ratio of 1.052, mediumentropy files 1.065, and low-entropy files 1.110. This pattern is displayed in Fig. 4.
high low medium
Entropy Level
Fig. 4. V3 Mean Expansion Ratio by Entropy Level.
Fig. 4 shows that low-entropy files have the highest average expansion ratio, while high-entropy files have the lowest. The absolute differences remain modest relative to the large reduction achieved from V1 to V3.
-
4.4. Runtime Scaling of the Final Framework
The full-corpus benchmark showed that V3 maintained low execution time across heterogeneous files. Mean encryption time across all 134 files was 0.000821 s, and mean decryption time was 0.000347 s. These values indicate that, at corpus level, the final framework imposed sub-millisecond average latency for both operations. Runtime nevertheless increased with file size, as expected from payload-dependent authenticated encryption. The relationship between file size and encryption time is displayed in Fig. 5.
-
4.5. Distributional Variation by File Characteristics
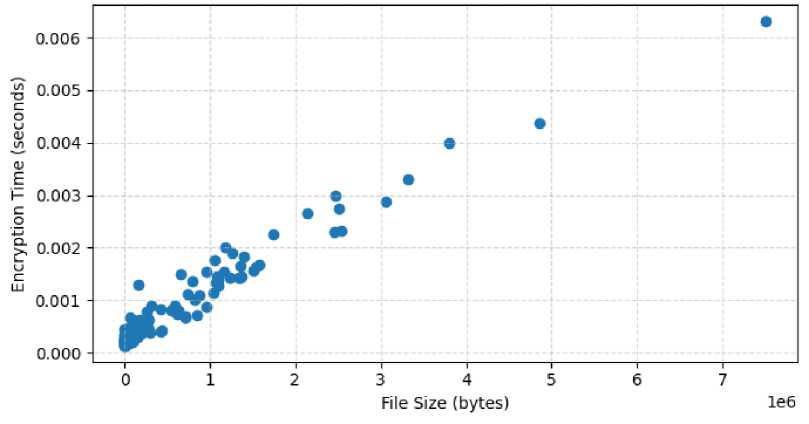
Fig. 5. V3 Encryption Time as a Function of File Size.
Fig. 5 shows a positive association between file size and encryption time. Smaller files cluster at very low latency values, while the largest files occupy the upper end of the observed range without abrupt discontinuities.
The same scaling logic was observed for decryption, although the absolute times remained lower than encryption times throughout the benchmark. Files in the largest size bucket contributed most to runtime variance, whereas files below 100KB were processed in very small fractions of a millisecond. No anomalous spikes or instability patterns were observed in the full-corpus execution log.
Beyond mean values, distributional analysis showed that expansion variability differed across file categories. Fig. 6 summarizes the distribution of expansion ratios by file type using boxplot statistics. DOC files were tightly concentrated near 1.0, indicating very limited dispersion. PDF and JPG files displayed moderate spread, with a small number of higher-overhead observations. TXT files showed the widest dispersion and the highest upper-range values.
Fig. 6. V3 Expansion-Ratio Distribution by File Type.
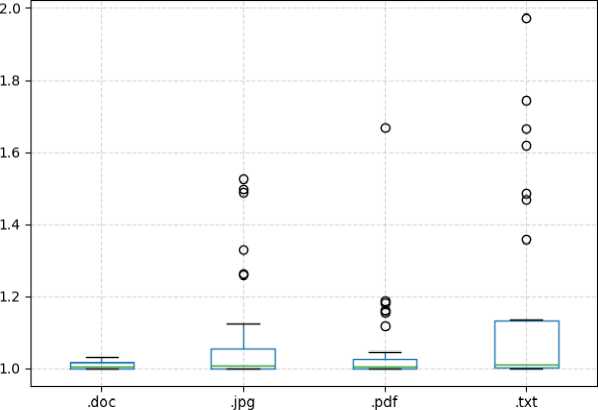
Fig. 6 shows that TXT files have the broadest expansion-ratio distribution, while DOC files remain tightly clustered. PDF and JPG files occupy an intermediate position with narrower interquartile ranges than TXT.
The broader TXT spread did not correspond to correctness degradation, because all TXT files were reconstructed exactly. Instead, the wider distribution coincided with the greater sensitivity of small text files to fixed cryptographic overhead. In the full benchmark, this effect was also consistent with the elevated mean expansion observed in the 1KB– 10KB bucket. Thus, the distributional variability was concentrated mainly in small-payload cases rather than being uniformly associated with any one format.
5. Discussion
The results show that the final V3 architecture has a compromise between quantum security for key establishment and operational efficiency for file protection that prior model generations of V3 failed to hold. What is crucial is not only that V3 outperforms V1 and V2 in terms of number of correct answers, but also because it is able to do so without making any errors in the entire evaluation set. This is important because while migration to post-quantum has been widely considered a security issue, the impact of implementing new cryptographic components is a significant challenge today. The present framework combines two important features: Kyber-based encapsulation and AES-GCM. The combination is in line with the transition logic that is accentuated by current standardization processes, in which the practicality of the hybrid is necessary for any real adoption and is not considered an afterthought to the algorithmic novelty [1].
The storage results are of significant importance. The high expansion ratios that are seen for the smallest files suggest that the major overhead is not due to uncontrolled growth in the ciphertext but instead is fixed cryptographic metadata. That is why the smallest files had the highest percentage gain: The length of the protected payload decreases, so the lengths of the KEM ciphertext, the nonce and the authentication tag do not. The larger size of this distribution for TXT files should therefore not be interpreted as a weakness of the format, but rather as a weakness of size, which is part of fixed overhead. The same applies to the higher compression of DOC and PDF files, which have higher average payloads, which dilute the costs of metadata. The authenticated-encryption behavior observed here is also consistent with what is expected from the design of GCM, which also provides integrity protection using a bounded structure regardless of the semantics of the application [4].
A comparative perspective helps explain the importance of a methodological point, the way one goes from V1 to V3. Direct post-quantum-style file encryption, as represented by V1, was functionally correct, but operationally inefficient, resulted in too much expansion and latency. V2 showed that there is great potential to significantly cut down those costs, but V2's custom construction, however, was less successful in aligning with established cryptographic standards. To retain these benefits in the transition from V2 to V3, the efficiency of hybridization was preserved, and the ad hoc mechanisms were replaced by standardised components. The same argument that is discussed in the transition literature, but is being reinforced in this case-namely, that the deployment of PQC is unlikely to occur at the same time as the replacement of all the cryptographic layers, and will more likely be carried out through well-designed architectures that integrate both PQC protection and the trusted use of existing symmetric encryption [7]. In this respect, the study contributes more to design for evidence-based transition engineering rather than primitive design.
The difference in the runtimes further supports the interpretation. All the above showed a continuous increase in the number of files in the heterogeneous corpus encrypted and decrypted. This type of behavior indicates that the cost of the framework is mainly equal to the cost of processing the payloads and not due to the interaction between the file structure and the cryptographic operations is unstable. This is in line with hardware and implementation tests that demonstrate that Kyber can be operated in a low latency manner, when implemented in an efficient system [13]. The present work, however, demonstrates that similar practicality is possible in a file-security setting, not with a set of very restricted benchmarks but with a real-world corpus instead.
The study has a number of limitations, however. The study evaluates system-level performance instead of providing a formal security reduction, and it uses a selected subset of GovDocs1 rather than the entire corpus. Furthermore, while Kyber is used as the post-quantum key encapsulation layer, the present analysis did not take into account side-channel or fault-injection testing. This is not a trivial omission since security in implementing Kyber is still a key issue to consider in such deployments [15]. Future studies should therefore integrate the current framework of file-level benchmarking with implementation-hardening analyses, repeated-run variant analyses of the final model and larger multi-corpus analyses. Further value could be added by considering the hardware assisted deployment paths, in particular, as optimized Kyber based platforms are already proving to be viable for operational environments [21].
6. Conclusion
This study presents and analyzes a practical file-security system based on post-quantum key encapsulation in combination with authenticated symmetric encryption, using a real-world, heterogeneous collection of files. The results show that a hybrid approach based on the standards can preserve exact file reconstruction with low storage overhead and very fast performance for a variety of file types, size ranges, and entropy conditions. In theoretical terms, the study is a part of the growing body of work on post-quantum transition by providing evidence of meaningful deployment improvements that can be achieved by integrating systems instead of just suggesting new cryptographic primitives. In practical terms, it demonstrates that post-quantum readiness for the protection of the file payload without the resulting heavy file inefficiency of trying to directly apply lattice-style encryption to files is possible. The results provide evidence that organizations aiming to become quantum secure with their storage and transmission should focus on a hybrid architecture where the session keys are protected by standardized post-quantum key encapsulation and the content of the files is secured by authenticated encryption. Future implementations should thus use tightly coupled components, use reproducible benchmarking pipelines, and test performance against real-world datasets and not synthetic ones. Concurrently, the study suggests there are four directions for future work: the use of repeated-run statistical analysis of the final architecture, a thorough side-channel and implementation-level security analysis, an expanded evaluation set of large and diverse corpora, and operational deployment path analysis for hardware-accelerated deployment. These directions can help to enhance the scientific development and readiness of post-quantum file-security systems as a whole.
All the Declarations and StatementsAuthor Contributions Statement
Moulay Ibrahim El-Khalil Ghembaza is the sole author and was solely responsible for all aspects of this research, including conceptualization, methodology, software implementation, data curation, validation, formal analysis, investigation, visualization, writing – original draft, writing – review and editing, and project administration.
Conflict of Interest Statement
The author declares no conflicts of interest.
Funding Declaration
The author expresses his sincere gratitude and appreciation to Onaizah Colleges, Saudi Arabia, for providing APC funding for this research.
Data Availability Statement
This study analyzed publicly available datasets. The GovDocs1 corpus used in this research is maintained by the Digital Corpora project and can be accessed at: , accessed on 25 July 2026. The source code supporting this study is available from the author upon reasonable request.
Ethical Declarations
This study did not involve human subjects, human data, or animals. No ethical approval was required.
Acknowledgments
I sincerely thank the experts for their professional evaluation and valuable recommendations, which have contributed to improving the quality of the experiment and the reliability of its results.
Declaration of Generative AI in Scholarly Writing
During the preparation of this work the author used Grammarly solely to check grammar, spelling errors, and improve language clarity. The author reviewed and edited all content and takes full responsibility for the accuracy, integrity, and originality of this publication.
Abbreviations
The following abbreviations are used in this manuscript:
NIST - National Institute of Standards and Technology
PQC - Post-Quantum Cryptography
AES-GCM - Advanced Encryption Standard in Galois/Counter Mode
FPGA - Field-Programmable Gate Array
GovDocs1 - Government Documents 1
KEM - Key Encapsulation Mechanism
Appendix
Not Applicable.
